
Data Annotation in Machine Learning: A Practical Beginner's Guide
Quick Answer
Learn data annotation in machine learning, from choosing labels and building QA workflows to video tracking and remote-work opportunities for Filipino beginners.
Table of Contents
- 1.1. Data Annotation in Machine Learning: What You Are Actually Teaching a Model
- 2.2. How to Select the Right Annotation Method for Your Machine Learning Project
- 3.3. Building a Data Annotation for Machine Learning Workflow That Produces Reliable Labels
- 4.4. Video Annotation for Machine Learning: A Practical Retail-Safety Example
- 5.Data Annotation in Machine Learning: Philippine Digital Workforce Context
- 6.Why Annotation Guidelines Matter More Than Labeling Speed
- 7.Frequently Asked Questions
An AI model cannot learn what a human team has failed to define clearly. Data annotation in machine learning is the practical work of turning raw images, text, audio, and video into examples a model can interpret. For Filipino learners, it is also a useful remote-work skill because it rewards careful reading, consistency, and sound judgment, not just fast clicking. Digital access continues to widen: 67.26% of the Philippine population used the internet in 2024, according to the World Bank, creating more pathways into online tools and distributed projects.
Data annotation in machine learning is the process of adding meaningful labels to raw data so a model can detect patterns and make predictions. In practice, a team defines the task and labels, writes annotation rules, labels a representative dataset, reviews quality, then exports the data in the format required by the ML team. Labels can be categories, bounding boxes, polygons, text spans, sentiment tags, transcriptions, or key points.
Table of Contents
- 1. Data Annotation in Machine Learning: What You Are Actually Teaching a Model
- 2. How to Select the Right Annotation Method for Your Machine Learning Project
- 3. Building a Data Annotation for Machine Learning Workflow That Produces Reliable Labels
- 4. Video Annotation for Machine Learning: A Practical Retail-Safety Example
- Data Annotation in Machine Learning: Philippine Digital Workforce Context
1. Data Annotation in Machine Learning: What You Are Actually Teaching a Model
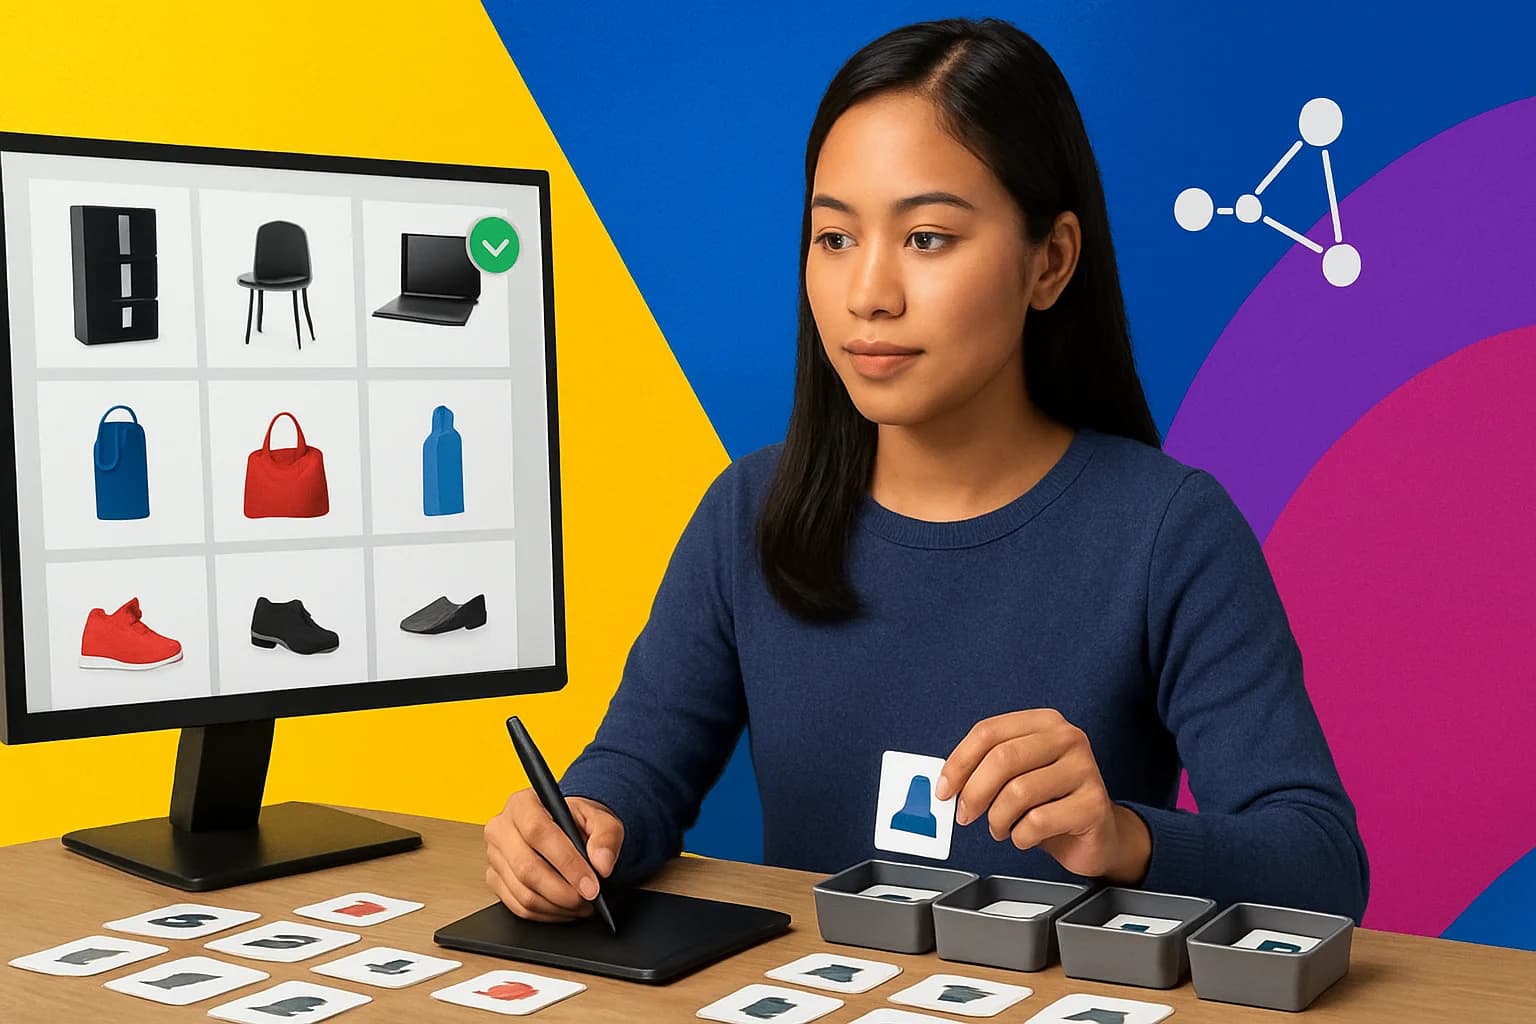
Raw data is information without an agreed meaning for the model. A folder of product photos is raw data. Once people label each photo as “shoe,” “bag,” or “other,” it becomes training data. During training, the model compares the image inputs with those labels and gradually learns patterns. Later, when shown a new photo, its output might be a predicted category and a confidence score.
This is the core of supervised annotation machine learning: people provide examples with known answers. Imagine an e-commerce store trying to sort uploaded listings. If every sneaker, sandal, boot, tote, and backpack is labeled consistently, the model can learn useful visual differences. If one annotator calls a canvas tote a bag while another calls it an accessory, the training signal becomes noisy. The model then learns uncertainty that the business did not intend.
The annotation method must match the question the model needs to answer. Classification assigns one or more labels to a whole item, such as “shoe present.” Object detection uses bounding boxes to show where each item is. Semantic segmentation marks the precise pixels belonging to an object. Named entity recognition highlights text such as a person, company, date, or location. Sentiment labeling marks whether a review is positive, negative, or neutral. Transcription converts spoken audio into text.
Annotation in machine learning matters even more in deep learning projects. Deep neural networks often need large volumes of labeled examples, and small definition errors can repeat thousands of times. Annotation deep learning work is therefore not merely clerical work. It is controlled decision-making at scale.

2. How to Select the Right Annotation Method for Your Machine Learning Project
Start with the model’s intended output, not the tool with the most buttons. Most people get this wrong. They open an annotation platform, see boxes and polygons, then work backward. Instead, ask: what must the finished system identify, locate, measure, or read?
- Use image classification when the answer is a simple presence or absence decision, such as whether a photo contains a damaged package.
- Use bounding boxes when the system must locate objects, such as pallets, helmets, or delivery vehicles.
- Use polygons or segmentation masks when irregular boundaries matter, such as road cracks, medical structures, or flooded areas.
- Use keypoints for pose estimation, such as shoulders, elbows, knees, or hand joints.
- Use text spans for names, dates, invoice numbers, and other entities within documents.
- Use audio transcription when a speech model needs the words spoken and, where needed, timestamps or speaker labels.
- Use frame-by-frame tracking when objects move through video and need a persistent identity.
Before beginning machine learning annotation, run through a short decision checklist:
- What is the data modality: image, text, audio, video, or a combination?
- What labels are allowed, and are they mutually exclusive?
- Can one item receive multiple labels?
- Which edge cases will appear, including blur, partial objects, slang, poor audio, or duplicates?
- What error level is acceptable for the use case?
- What output format does the ML team require: JSON, CSV, COCO, YOLO, or a platform export?
A model that only needs to know whether a helmet exists does not need a precise polygon around it. Conversely, a safety system that must measure whether a worker’s hand is inside a hazardous area may need pixel-level masks. Good machine learning data annotation uses the least complex label type that still supports the business goal.
3. Building a Data Annotation for Machine Learning Workflow That Produces Reliable Labels
A reliable data annotation for machine learning workflow begins before production. First, audit a representative sample. Do not inspect only clean, obvious files. Look for poor lighting, unusual camera angles, mixed languages, duplicates, incomplete documents, and other conditions that will create disagreements later.
- Create a label taxonomy with clear definitions.
- Write an annotation guide with written rules and visual examples.
- Run a small pilot batch with more than one annotator.
- Review the pilot and rewrite unclear rules.
- Train annotators on the final guide and feedback process.
- Label production batches.
- Conduct blind review, where reviewers assess work without being influenced by the original annotator.
- Resolve disagreements and record the decision.
- Version both the dataset and the guideline before delivery.
Consider a delivery-app image project with three labels: motorcycle, rider, and delivery bag. The rules must say whether a partly hidden motorcycle counts, whether a rider seen only from the shoulders up is labeled, and whether two visible bags are separate instances. They must also explain whether a bag reflected in a shop window is ignored. Without those choices, two conscientious annotators can produce different labels from the same image.
Inter-annotator agreement is simply a way to check how often qualified annotators reach the same conclusion under the same instructions. Low agreement does not automatically mean the team is careless. It often reveals that a category is vague, an edge case is missing, or the source material is genuinely unclear. QA should deliberately sample difficult cases, not just easy labels that make a quality report look impressive.
This discipline is valuable for remote workers. The Philippine Statistics Authority reported a 12.9% underemployment rate in July 2026, according to the Philippine Statistics Authority. In a competitive market, a portfolio showing a pilot guide, edge-case decisions, and quality review is more persuasive than the generic claim, “I am detail-oriented.” Data annotation machine learning projects need people who can explain why a label was chosen.

4. Video Annotation for Machine Learning: A Practical Retail-Safety Example
Video annotation for machine learning adds a time dimension. Suppose a retail chain wants a system that flags wet-floor warning signs and unsafe aisle obstructions from CCTV footage. The goal is not simply to recognize an object in one attractive frame. The model must cope with shoppers walking past, carts blocking the view, motion blur, changing light, and signs that enter or leave the scene.
A practical workflow starts by extracting clips or frames and defining object classes, perhaps “wet-floor sign,” “obstruction,” and “clear aisle.” Annotators draw boxes when a rough location is enough, or polygons when the exact occupied floor area matters. Each tracked sign or obstruction receives a persistent ID across frames. The annotation guide should specify how to handle occlusion, such as keeping an ID while an object is briefly blocked, and when motion blur makes an object too uncertain to label.
Frame-by-frame labeling is necessary when movement, duration, or identity is central to the output. For example, tracking whether an obstruction remains in an aisle for 10 seconds requires continuity. Sampling every fifth or tenth frame can be enough when the project only needs varied examples of objects and small movement between frames will not change the result.
The tradeoff is real: video work takes more time because consistency must hold across frames, not only within one image. Sensitive CCTV footage also requires access controls, minimization of personally identifiable information, and clear instructions on faces, customer details, and retention. Careful handling is part of quality, not a separate legal task someone else will solve later.
Data Annotation in Machine Learning: Philippine Digital Workforce Context
The figures below describe the broader Philippine labor market, not the size of the annotation workforce. The country had a labor force of 52.358 million people and a 6% unemployment rate in July 2026, according to the Philippine Statistics Authority. For beginners, the useful takeaway is not to assume every online labeling task is a fit. Assess the actual task requirements, tool familiarity, English comprehension, data sensitivity, and QA expectations before pursuing annotation work.
Source: World Bank Open Data
Why Annotation Guidelines Matter More Than Labeling Speed
The expensive failure is usually not a slow team. It is a fast team applying different interpretations of the same label. A vague instruction like “label every car” sounds simple until annotators encounter a reflection of a car in glass, a parked vehicle cut off by the image edge, a toy car, or a car inside a billboard advertisement. Each case needs an explicit answer.
Create a living guideline document with inclusion rules, exclusion rules, edge-case examples, a decision log, and version numbers. A useful rule may say: label real road vehicles that are at least 30% visible; exclude reflections, toys, illustrations, and advertisements; label partially visible vehicles only when the vehicle class is reasonably identifiable. That is far more usable than telling people to “use common sense.”
When a rule changes, earlier labels may need rework. Preserve guideline versions alongside dataset versions so the ML team knows exactly which definition produced each batch. This habit separates dependable annotation work from rushed labeling. Speed improves with practice, but a clear shared interpretation is what makes the dataset trustworthy.
Frequently Asked Questions
What is data annotation in machine learning?
It is the process of labeling raw data so machine learning models can learn from examples. Labels can include image categories, bounding boxes, segmentation masks, text entities, sentiment tags, audio transcriptions, and video tracking IDs.
What skills do I need to start data annotation work?
You need strong attention to detail, reading comprehension, consistency, basic computer skills, and the ability to follow written guidelines. Tool experience helps, but understanding label definitions and QA feedback matters more than clicking quickly.
What is the difference between image annotation and video annotation?
Image annotation labels one still image. Video annotation must keep labels consistent across many frames and may require object tracking, persistent IDs, and decisions about occlusion or motion blur.
How do annotators check data quality?
Teams use pilot batches, reviewer checks, blind samples, disagreement resolution, and documented edge-case decisions. Quality review should focus on difficult and ambiguous examples, not only obvious labels.
You might also like
More guides on Annotation Machine Learning.
Active Learning for Data Annotation: A Practical Workflow Guide
Learn how active learning for data annotation helps remote teams prioritize informative examples, improve label quality, and avoid costly selection bias.
Data Annotation Machine Learning: Build Better Training Data
Learn how data annotation machine learning workflows define labels, improve quality, manage video projects, and build reliable training data at scale.
Latest Virtual Assistant Jobs
Fresh remote VA roles — apply directly
Sales Development Representative - Remote - Welo Global
Join Welo Global as a Data Rater - Remote Opportunity
Senior Talent Acquisition Partner at Veeam Software - Hybrid
Insurance Sales Representative - Remote - RemoteHub